 BBC
- Token prices have plummeted, but consumption has skyrocketed, with token use expected to increase 24 times between 2026 and 2030.
- Firms like Saviynt and Sumo Logic find it hard to set prices for AI services because token costs are non-deterministic and change frequently.
- Microsoft and Uber exceeded their AI coding token budgets, highlighting the difficulty of managing costs.
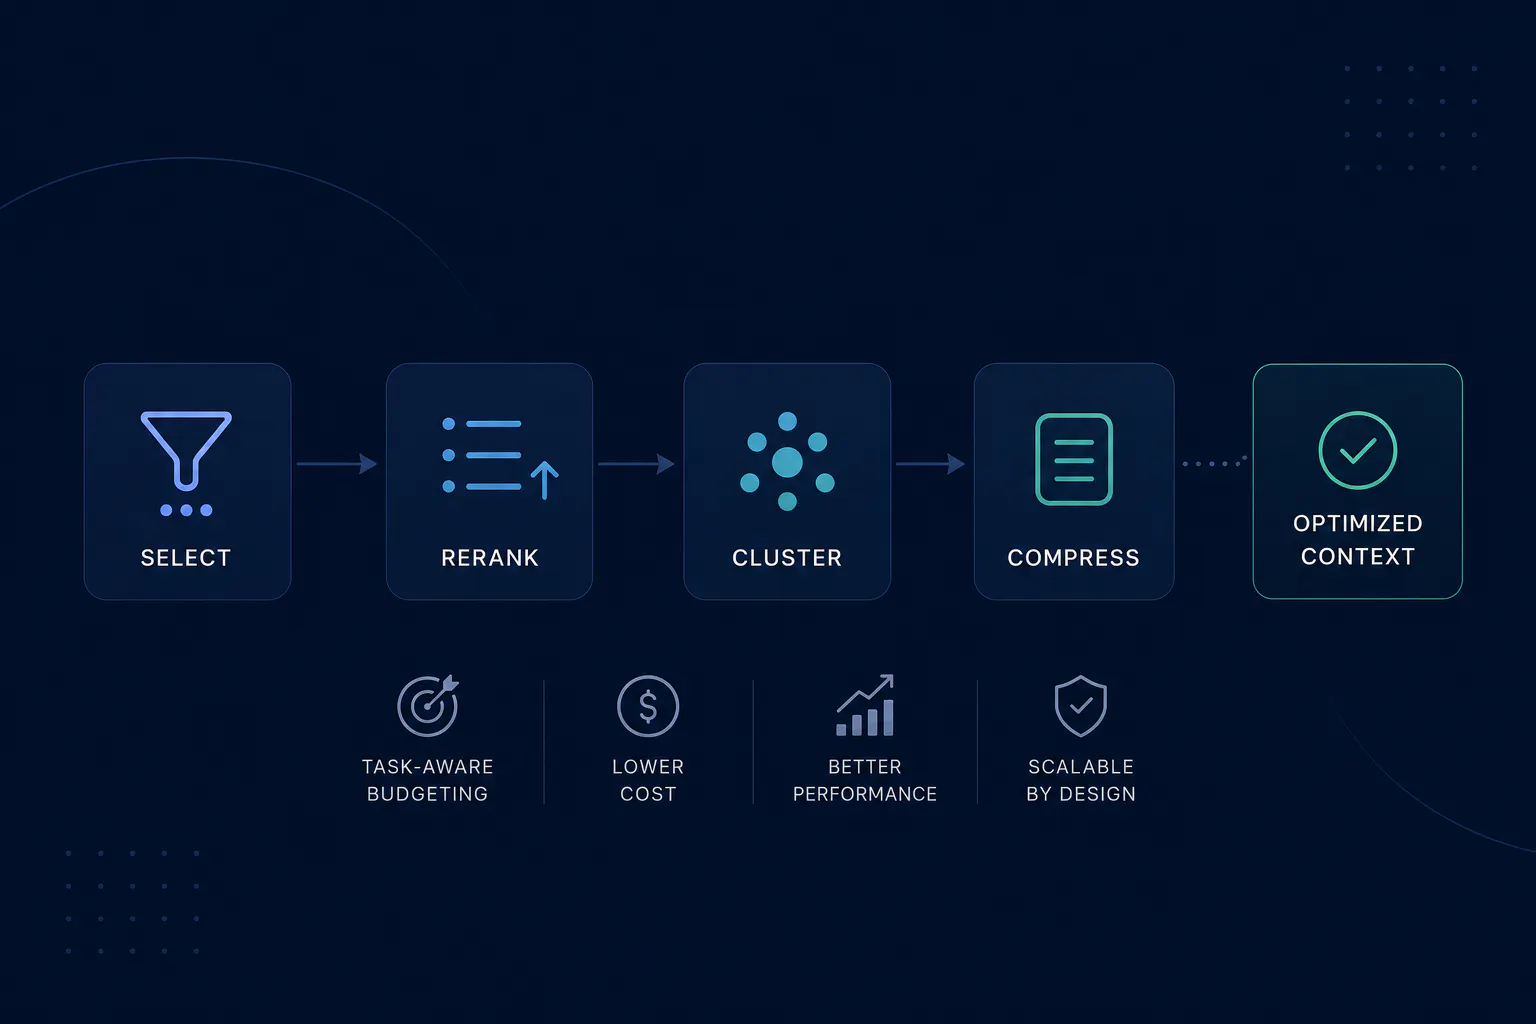
- A context engineering layer that forecasts token budgets per task reduces input context by 60-80% per call, cutting mean tokens per task by up to 95% across models.
- Quality either holds or improves for most models, but Gemini's task success drops from 75% to 40% under a fixed budget, showing the need for task-aware forecasting.
- Token consumption will increase significantly as companies shift to use AI agents, leading to challenges in managing costs.
- AI costs could start to balloon as managers realize they need tokens for various tasks beyond core software development.
AI pricing is a growing challenge as fluctuating token costs complicate budgeting for businesses. With token consumption projected to increase 24 times by 2030, companies are struggling to manage expenses.12348
Context engineering offers a promising solution, reducing token usage by up to 95% without compromising quality. This technique involves a forecasting layer that sets a budget for token use before tasks are executed, significantly lowering costs.
For instance, the median task cost dropped from 58k tokens to 24k tokens with this method, while task success rates improved from 32% to 42%.
However, the unpredictability of token consumption remains a concern. As Simon Gooch from Saviynt notes, “People are finding it really hard to manage that cost… it's a non-deterministic output.”
Smaller organizations may exploit flat-fee accounts, but industry experts warn that this practice may not last as larger companies seek profitability.
The need for precise prompts is critical, as Rob Steele from iplicit emphasizes, “You wouldn't send someone in your family out to get the weekly shop without any kind of detailed instructions.”
As AI integration expands, companies must adapt to these challenges to avoid ballooning costs.
“Token consumption is projected to grow 24-fold by 2030, reaching 120 quadrillion tokens monthly, as firms shift to AI agents. Meanwhile, a context layer that trims 60-80% of input per call lifted task success from 32% to 42% on the main agent, though Gemini's success fell from 75% to 40% under a fixed budget.”
 HackerNoon